Voice AI
Semantic Search for Voice Agents
From voice agents to AI copilots, Moss gives your product <10ms semantic retrieval without managing vector infrastructure.
I need to reschedule my appointment
Does next Tuesday work?
Yes, please.
<10 ms
P99 retrieval latency
0 ms
network round-trips
100x
faster than cloud vector DBs
Your voice agent needs context in under 10 milliseconds.
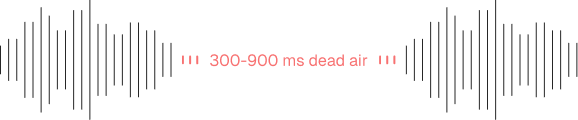
Network round-trips to cloud vector databases add 300-900ms of dead air. Moss runs retrieval locally, inside your agent runtime, so your agent responds without the pause.
The Problem
Dead air kills voice agents
Traditional RAG sends retrieval over the network to Pinecone or Qdrant — and round-trips mean silence. Users notice gaps as short as 200ms. The LLM was never the bottleneck. Retrieval is.
How Moss Solves This
1
Local retrieval, zero network hops
Moss runs search inside your agent runtime. No network round-trip to a cloud database. Retrieval completes in under 10ms, locally.
2
Built for streaming conversation
Designed for the real-time loop of ASR, retrieval, LLM, and TTS. Moss fits into the critical path without adding perceptible latency.
3
Works with every voice stack
Drop-in integration with LiveKit, Pipecat, VAPI, ElevenLabs, and Hume AI. Install the SDK and start querying in minutes.
Ship real-time retrieval in minutes
from moss import MossClient

client = MossClient(PROJECT_ID, PROJECT_KEY)

docs = [{ "text": "How do I track my order?" }]

await client.add_docs("my-index", docs)
Frequently asked questions
Ready to ship faster AI products?
Moss gives you production-ready semantic retrieval without infrastructure complexity.