


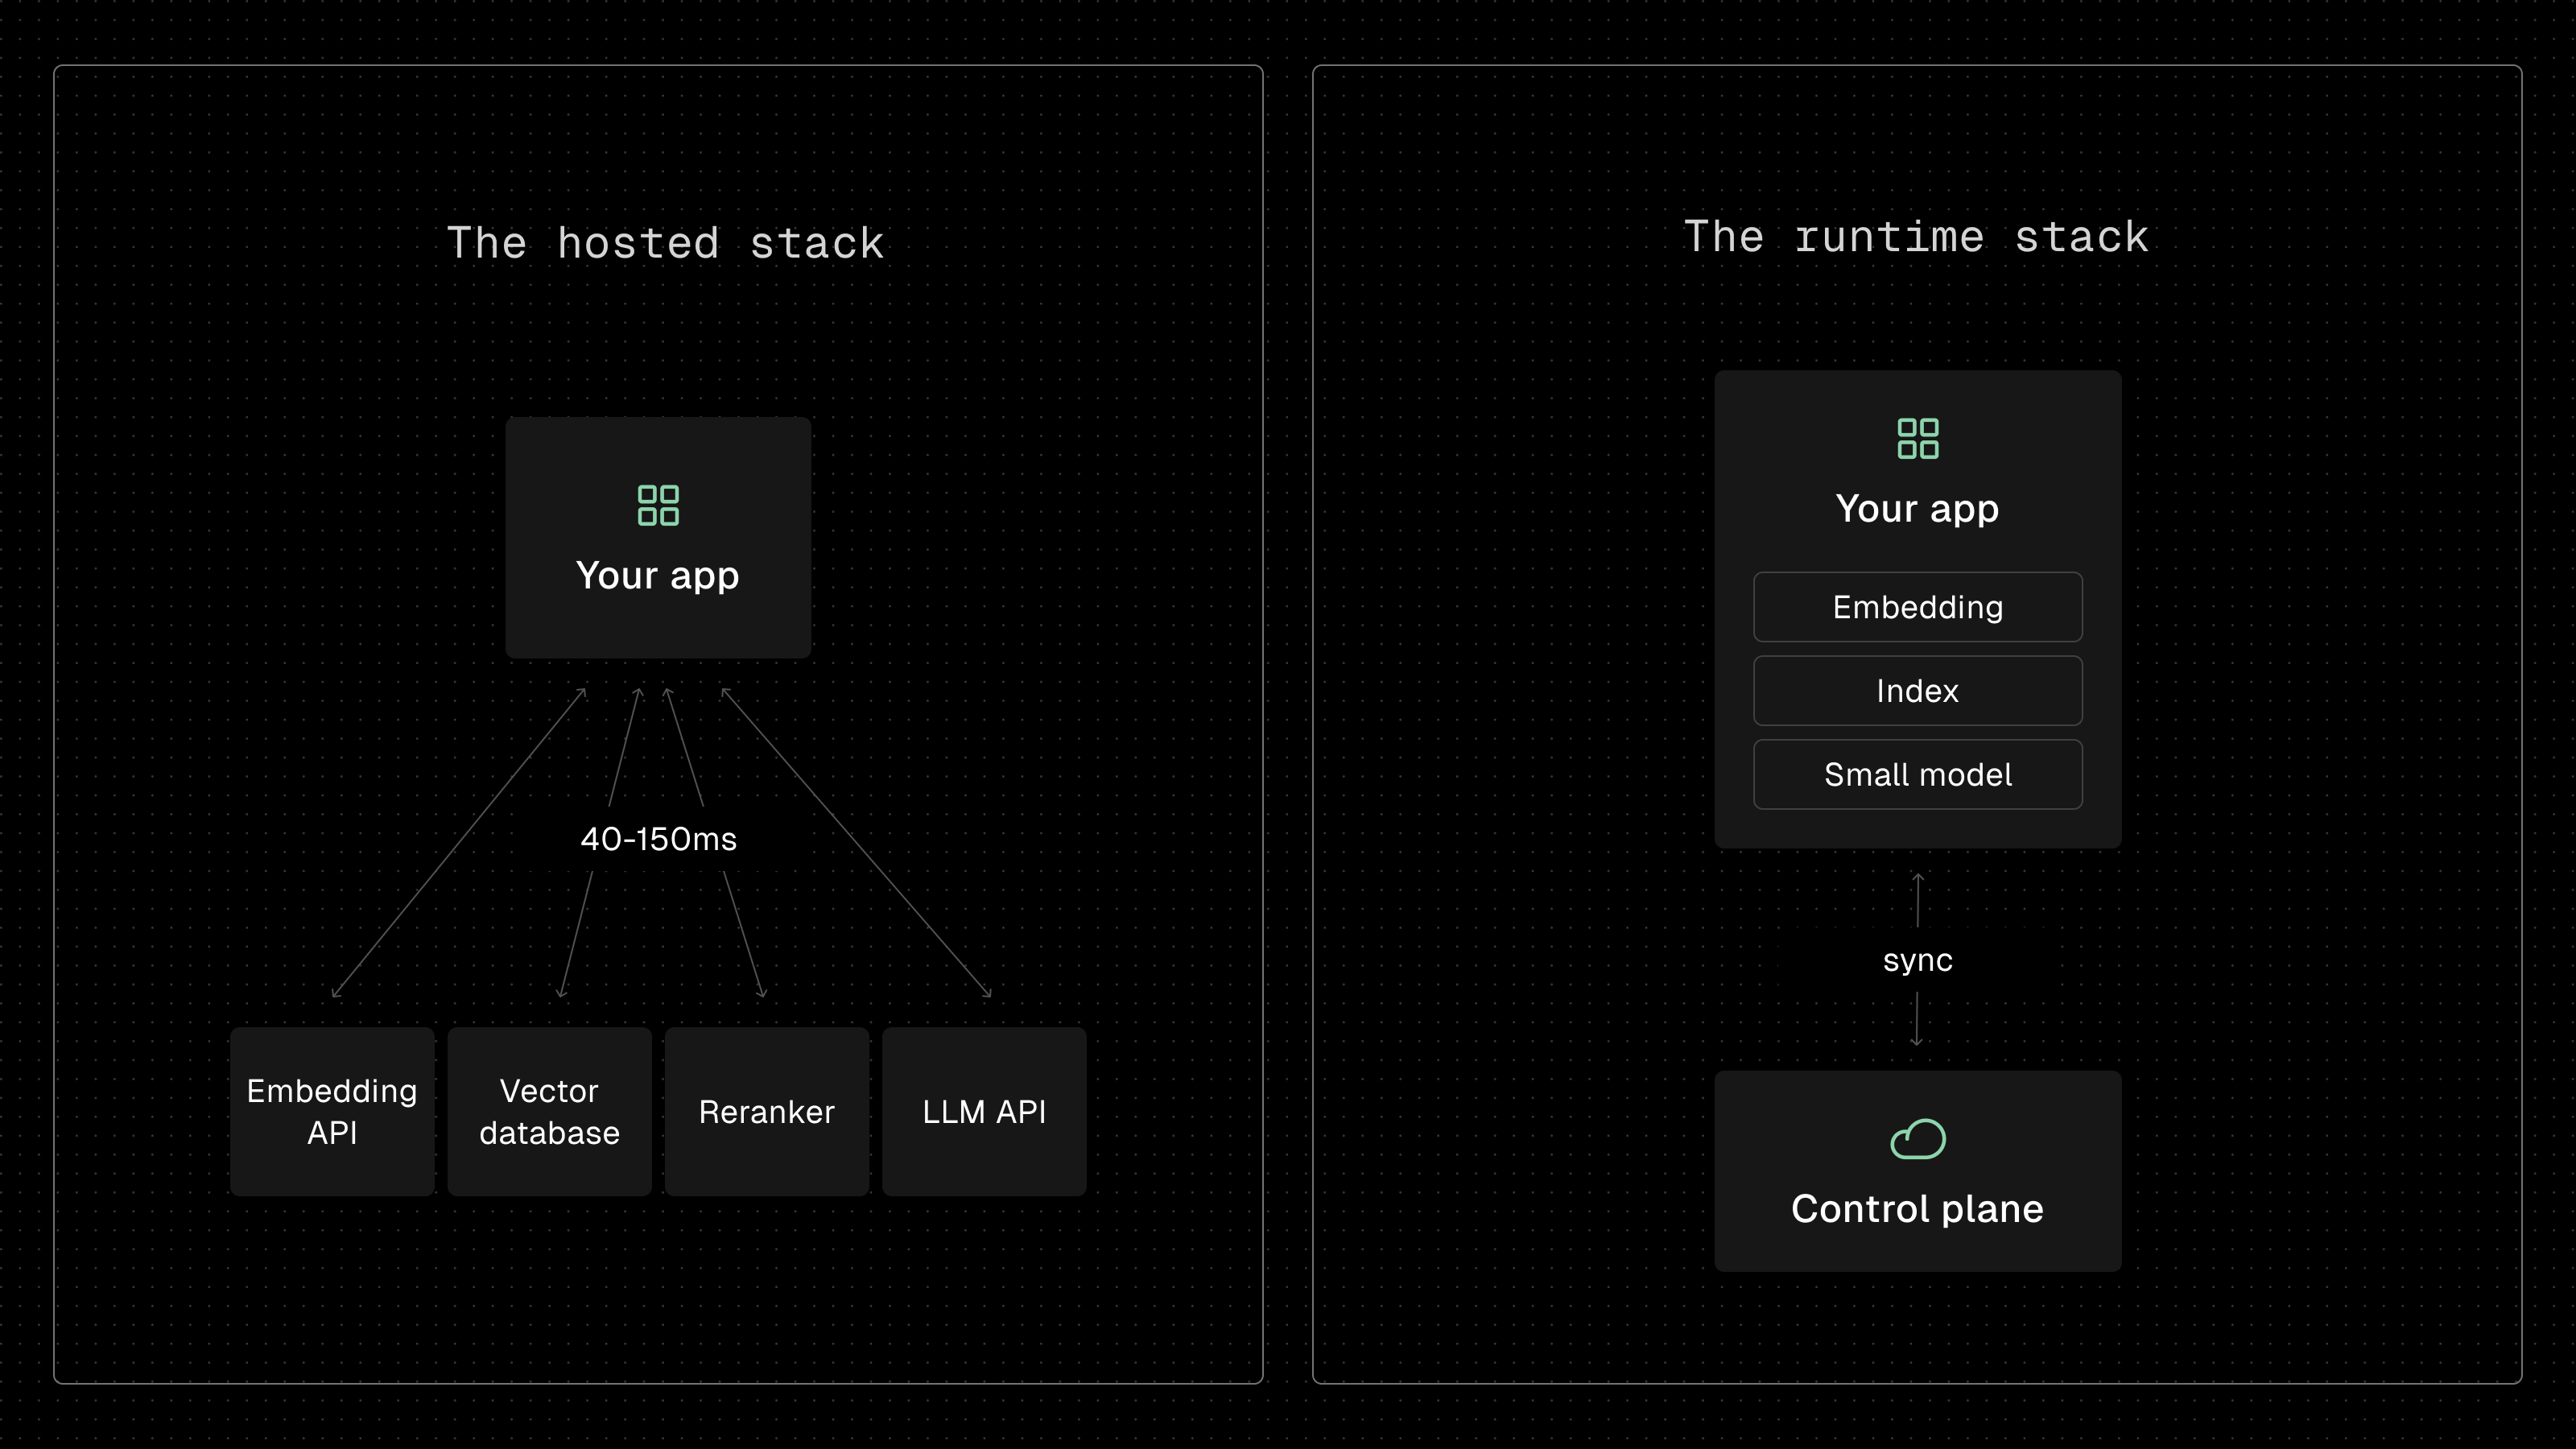
Open the architecture diagram for a typical AI feature in 2026 and count the boxes. The application is one of them. Around it sit an embedding API, a hosted vector database, a reranking endpoint, and an LLM API, all in someone else's cloud, each billed separately and a network hop away from the code that needs it. Four extra services for a single feature, and for many teams, that architecture emerged incrementally rather than from a deliberate decision.
None of those services is a bad product, and the stack they form works. What makes it worth examining is that the rest of the developer stack used to look exactly like this, then stopped, and nobody misses the old shape. AI infrastructure has started down the same path, and the reasons change how production AI systems get built.
Every Layer Eventually Becomes a Library
The most deployed database in the world ships as a library. SQLite is linked into every iPhone, every Android device, every major browser, and most operating systems, with nothing to connect to. Its win came from refusing the client-server model, at least for the enormous class of workloads that never needed one.
DuckDB repeated the move for analytics, running columnar queries inside your process over files already on your disk, at speeds that used to justify a warehouse. Once that worked, the warehouse round trip became optional for everything below true big-data scale.
The newest twist is the synced local copy. Turso's embedded replicas keep a full SQLite file inside your application and sync it against a remote primary, so reads happen locally in microseconds while the network only gets involved when synchronization requires it.
Caching followed the same curve from memcached clusters to in-process caches, and compute itself moved to the edge to sit next to the user, every layer heading the same way, into the runtime.
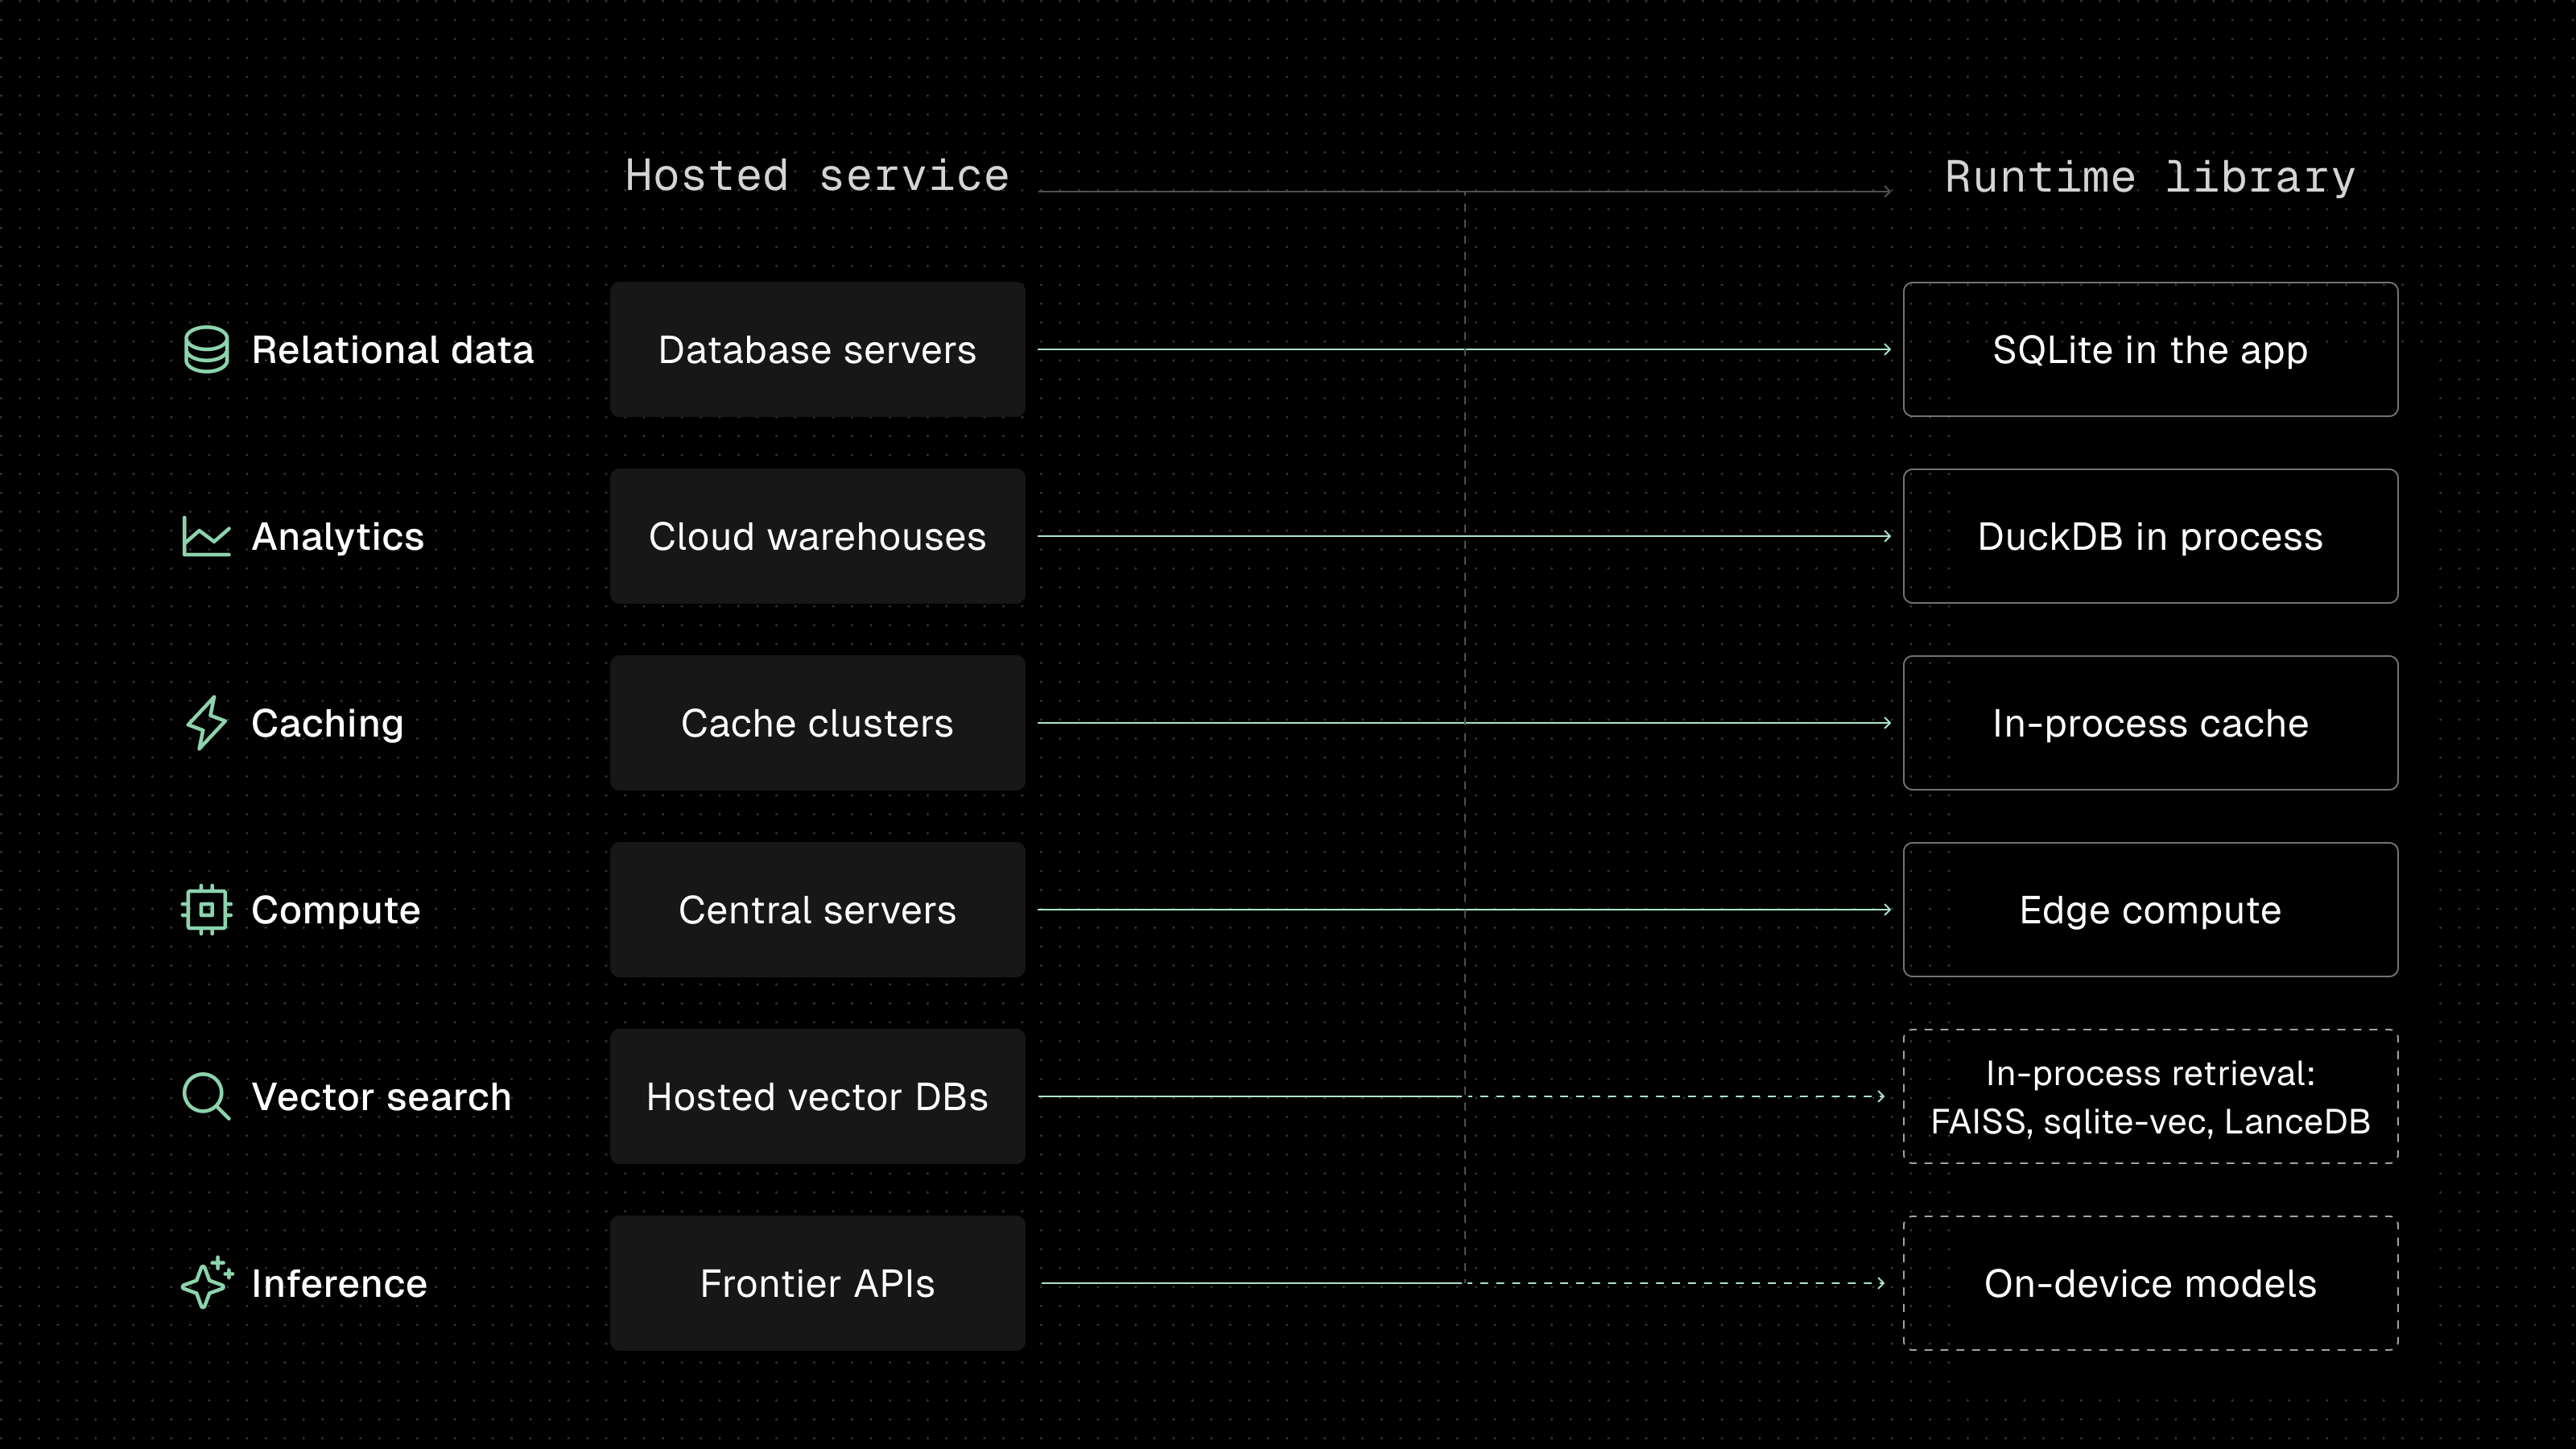
Hold that pattern up against AI infrastructure and most of the matches are already filled in.
| Capability | Hosted era | Runtime era |
|---|---|---|
| Relational data | Database servers | SQLite linked into the app |
| Analytics | Cloud warehouses | DuckDB in-process |
| Caching | Managed cache clusters | In-memory caches inside the service |
| Compute | Centralized servers | Compute at the edge |
| Vector search | Hosted vector databases | In-process retrieval: FAISS, sqlite-vec, LanceDB |
| Inference | Frontier models behind APIs | Small models in OS runtimes and on device |
The bottom two rows are the ones being written right now, for the same three reasons the others crossed: performance, cost, and developer experience.
Performance: The Physics of the Network Hop
Reading from local memory takes around 100 nanoseconds, a round trip inside one datacenter costs around half a millisecond, and a round trip across a continent can cost around 150 milliseconds. Several orders of magnitude separate the first number from the last, and no amount of engineering on the far side of the socket can refund them.
Whether that matters depends on what you are building. A batch job never notices, but an interactive AI product lives inside those numbers. We covered what this does to retrieval in The Retrieval Latency Tax, so the short version here is that a call that looks fast on the provider's dashboard is still slower by the time it has crossed the network twice, and the crossing is the part users feel.
Latency also compounds in a way dashboards hide. An agent that makes five hosted calls per turn pays the sum of the hops rather than the average, and at P99 it pays the worst of each.
Cost: Paying Retail for Compute You Already Own
Hosted AI services do the compute for you and charge for it with a margin. An embedding API and a managed vector database each run your workload on machines the vendor rents, and every price has to cover those machines plus the vendor's cut. Your own servers and your users' devices sit mostly idle while you pay for that second fleet.
A runtime moves some or all of that compute onto infrastructure you already have. You may still pay for storage, sync, and usage, but the heaviest part of the work, the per-query compute, now runs on hardware whose cost you were carrying anyway, which can make the total cheaper.
Developer Experience: Setup Becomes a Package Install
The third argument is developer experience. Setting up a local package is usually easier than setting up infrastructure somewhere else, and libraries like SQLite and FAISS show how little it takes: one install command, one import, and your first working call. From there it's ordinary code inside your own project.
It also gives you back a laptop that works. An AI runtime that embeds, indexes, and queries in-process can behave the same in CI, on a plane, and in production, and the version you tested is the version you ship, pinned in your lockfile.
There is also one less thing that can go down. A hosted retrieval service can have an outage while your app is perfectly healthy, and your users still see a broken product. A library in your process has no separate status page: if your app is up, search is up.
Retrieval Moved First
Vector search is the clearest case, because it has run through much of the arc in about three years. It began as a product category with dedicated hosted databases, and then the databases teams already ran absorbed it, natively in MongoDB, Redis, and SQL Server, and through the pgvector extension in Postgres. For many teams, vector search turned into a feature of the database they already had.
The next step is in progress: retrieval as a library. FAISS was always an in-process engine, sqlite-vec puts vector search in a single file with no daemon to run, and LanceDB is built for embedded and edge use. For many production workloads below tens of millions of vectors, retrieval can fit inside the process that needs it.
This is the step Moss is built for. A bare library hands you the index and leaves embedding, packaging, and keeping the data fresh as your problem, so we built the whole retrieval path to run in-process, embedding inference included. In our benchmark, a query over a 100,000-document index returns in 3.1 ms at P50 and 5.4 ms at P99. Numbers like that are what a query can cost once no network sits on the request path, with no exotic engineering required.
The Operating System Is Now an AI Runtime
Inference is following, and the push is coming from an unexpected direction: the platforms themselves. Apple's Foundation Models framework makes an on-device model available to iOS apps through a system API, and supported workloads can run without a network round trip. Android exposes Gemini Nano to apps as an operating system service, Chrome ships a built-in model behind its Prompt API, and WebGPU inference in the browser is becoming increasingly viable.
The routing is the tell: on-device and cloud are becoming more interchangeable behind a runtime interface.
The developer side is keeping pace. Local inference tools have made running models on developer machines dramatically simpler, while model hubs now offer a large and growing selection of models packaged for local inference. The broader shift is toward matching the model to the task: many agent invocations are small, repetitive tasks that do not require a frontier model, making smaller models attractive on device and at the edge.
Edge AI used to describe an exotic deployment target, and increasingly it describes where inference can be cheapest and fastest to run.
Real Time Is the Forcing Function
Cost and developer experience make the runtime attractive, and real-time products make it unavoidable. A voice agent has roughly 800 ms to start speaking before the pause reads as broken, and a stitched pipeline of hosted services can burn 50 to 200 ms of that budget on network hops alone, before any model has done any work. We broke the full turn down in Building Voice AI That Feels Human.
The teams shipping voice agents, live copilots, and in-editor completion are moving infrastructure into the runtime because the latency budget leaves them nowhere else to put it.
What Still Belongs in the Cloud
The shift has edges, and pretending otherwise would be selling something. Frontier-scale inference stays centralized, since the largest models need multi-node GPU clusters and the cloud economics of continuous batching and disaggregated serving are what make those tokens affordable. Very large vector indexes with heavy write churn can still benefit from a dedicated hosted engine, and an index living inside your process competes with your application for memory, which is a real cost on small devices.
There are operational edges too. Durability, backup, cross-device sync, and fleet-wide observability are things a runtime can't give itself, and when queries never touch your backend, knowing what your product is doing takes deliberate design.
The cloud keeps a large and permanent job while the request path moves out, workload by workload.
The Cloud Becomes the Control Plane
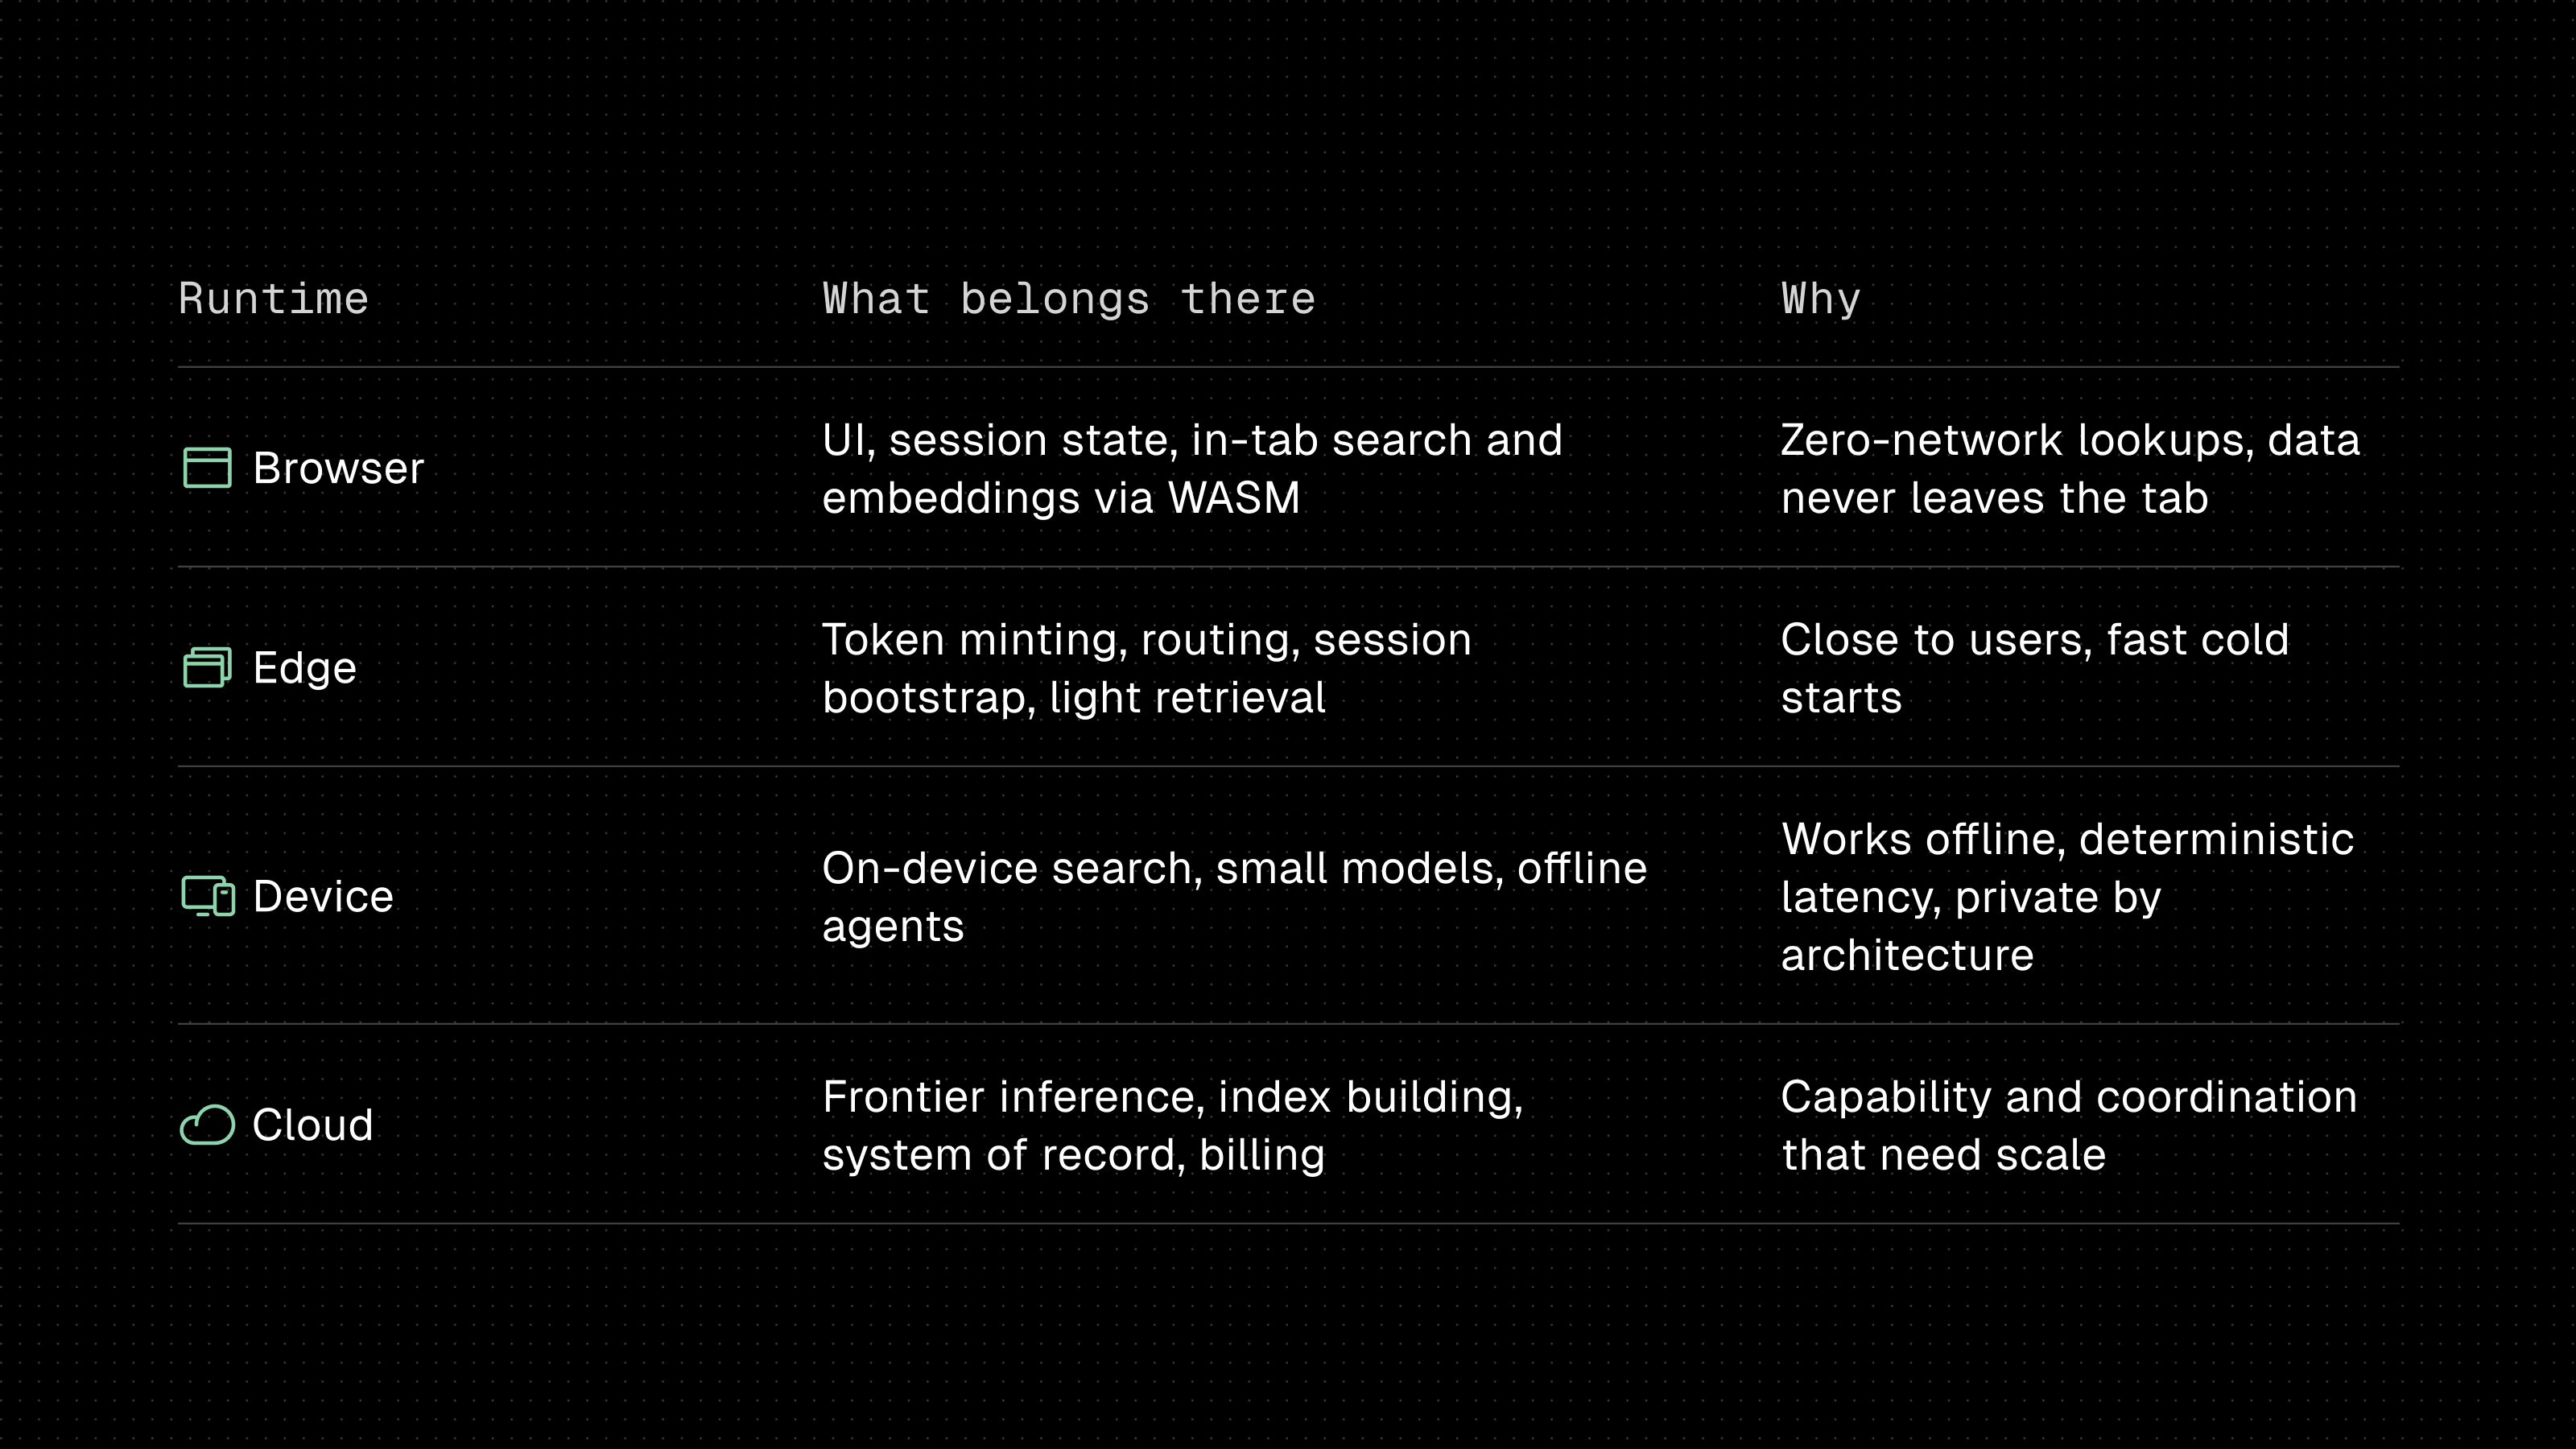
The cloud becomes the control plane that trains and packages models, builds and stores indexes, syncs artifacts to wherever the application runs, meters usage, and coordinates fleets, while the runtime becomes the data plane that holds the working set and answers on the request path, in-process, in microseconds to low milliseconds.
It is the shape we build Moss around: the cloud builds and stores the index artifact, your process pulls it at load time and can poll for newer versions in the background, hot-swapping them with no query downtime, and every query runs inside your process. The control plane is what makes the runtime deployable at fleet scale.
The Diagram Gets Simpler
Each box on that opening architecture diagram survives the move. What changes is where it lives: inside your application, as code, with one quiet line back to the cloud for sync.
The database, the warehouse, and the cache all made this move before, and each time the diagram got simpler while the product got faster and cheaper. AI infrastructure is starting to follow the same path. The best AI infrastructure, like the best latency, is the kind that stops showing up in your diagram.


